Data management basics for student researchers
Princeton Journal of Pre-Collegiate Research
Data management basics for student researchers
Poor data management is one of the most common reasons student research papers fail peer review, yet most guides on conducting research treat it as an afterthought. A study published by the Research Data Alliance found that a significant proportion of research data becomes uninterpretable within five years due to inadequate documentation and inconsistent file organization. For high school researchers, the consequences arrive far sooner: disorganized data leads to analytical errors, unreproducible results, and reviewer rejections that could have been avoided. This post covers data management basics for student researchers from the point of data collection through to submission, with specific attention to the mistakes that cost otherwise strong papers their acceptance.
What are data management basics for student researchers?
Data management for student researchers refers to the systematic process of organizing, labeling, storing, and documenting research data so that results are accurate, reproducible, and verifiable by an independent reviewer. At minimum, this involves a consistent file naming convention, a version-controlled master dataset, a codebook defining every variable, and a documented audit trail from raw data to final analysis. These four elements are sufficient to meet the reproducibility standards expected by peer-reviewed journals.
The distinction between raw data and processed data is the first concept every student researcher must internalize. Raw data is the unmodified output of measurement: survey responses as collected, sensor readings as recorded, interview transcripts as produced. Processed data is what results after cleaning, coding, or transformation. These two categories must always be stored separately. Overwriting raw data is the single most consequential data management error a student researcher can make, because it eliminates the possibility of independently verifying the analysis.
File naming is the second foundational element. A file named finaldata2.xlsx communicates nothing about its contents, its version, or its relationship to other files in the project. A file named survey_responses_raw_2024-11-03_v1.xlsx communicates the data type, its state (raw), the date of collection, and its version number. This level of specificity is not pedantic. It is what allows a peer reviewer, a mentor, or the researcher themselves six months later to reconstruct exactly what was done and in what order.
Variable documentation is the third element. Every column in a dataset must be defined in a separate codebook: the variable name, what it measures, the units used, the permissible values or range, and any coding decisions applied (for example, how missing responses were handled). Without a codebook, a dataset is interpretable only by the person who created it. Peer reviewers and journal editors cannot assess the validity of an analysis conducted on undocumented variables. Students working in the social sciences, psychology, or public health will encounter this requirement explicitly in journal submission checklists. Those working in biology or environmental science will encounter it in the methods section expectations reviewers apply.
Students preparing a submission can review how published papers in their field handle data documentation by browsing published issues at the Princeton Journal of Pre-Collegiate Research, where methods sections provide concrete models of how student researchers have described their data collection and organization procedures.
What should student researchers do after collecting their data?
The period immediately following data collection is when most organizational failures occur. Students who have spent weeks or months designing and running a study often shift their attention directly to analysis, skipping the documentation steps that make that analysis defensible. The consequence is not immediately visible. It surfaces during peer review, when a reviewer asks how a specific variable was coded or how outliers were handled, and the researcher cannot provide a documented answer.
The correct sequence after data collection is: lock the raw data file (make it read-only or store it in a location that is not edited), create a working copy for cleaning and analysis, document every cleaning decision in a change log, and update the codebook to reflect any recoding decisions made during cleaning. This sequence takes between one and three hours for a typical student research dataset. It eliminates the category of reviewer objection that begins with the phrase "the authors do not appear to have documented."
Version control is a related requirement that students frequently underestimate. Saving successive versions of an analysis file as v1, v2, v3 with dated filenames is sufficient for most student research projects. More advanced researchers may use Git, a free version control system supported by platforms such as GitHub, which maintains a complete history of every change made to a file. The Research Data Management guidance published by the UK Data Service recommends version control as a baseline practice for all empirical research, regardless of scale. For student researchers submitting to peer-reviewed journals, the ability to show that the analysis proceeded in a documented, sequential manner strengthens the credibility of the reported results.
Students who want to understand how reviewers evaluate the relationship between raw data and reported findings can read more about what reviewers look for in student research at the PJPCR blog post on data vs. evidence: what reviewers look for in student research.
What are the most common data management mistakes student researchers make?
The four mistakes below account for the majority of data-related objections raised during peer review of student research papers. Each is specific, correctable, and more common than students expect.
The first mistake is overwriting raw data. Students who import survey responses into a spreadsheet and immediately begin deleting rows, recoding values, or reformatting columns are destroying the evidentiary foundation of their study. The fix is simple: before any editing begins, save a copy of the original file in a folder labeled raw and do not open that folder again except to verify the original values.
The second mistake is inconsistent variable naming. A dataset in which the same variable appears as Age in one column, age_years in another, and participant_age in a third is not a dataset that can be analyzed reliably. Statistical software treats these as three different variables. Reviewers reading the methods section cannot reconcile them with the reported results. The fix is to establish a naming convention before data entry begins and apply it without exception.
The third mistake is undocumented exclusion decisions. When a student removes a data point because it appears anomalous, that decision must be recorded: which observation was removed, on what grounds, and whether the exclusion was pre-registered or post-hoc. The American Psychological Association's reporting standards, which apply across many social science disciplines, explicitly require that exclusion criteria be stated in the methods section. Reviewers who find that reported sample sizes do not match collected sample sizes without explanation will typically request major revisions or reject the paper outright.
The fourth mistake is storing data in a single location without a backup. Hard drives fail. Cloud accounts are accidentally deleted. A research project that exists only on one device is one hardware failure away from total loss. The standard practice is the 3-2-1 rule: three copies of the data, on two different media types, with one stored off-site or in the cloud. For student researchers, this means the original file on a local drive, a copy on a cloud service such as Google Drive, and a copy on an external drive or a second cloud account.
How to apply data management basics for student researchers, step by step
Create a project folder structure before data collection begins. At minimum, include subfolders labeled raw_data, processed_data, analysis, outputs, and documentation. This structure should be established on the first day of the project, not after data has been collected.
Write a codebook before entering any data. Define every variable: its name, what it measures, its units, and its permissible values. Update the codebook whenever a recoding decision is made during cleaning.
Lock the raw data file immediately after collection. Set the file to read-only or move it to the raw_data folder and do not edit it. All subsequent work is performed on a clearly labeled working copy.
Document every cleaning decision in a change log. A simple text file listing the date, the change made, and the reason for the change is sufficient. This log is the audit trail that peer reviewers may request.
Apply the 3-2-1 backup rule. Store three copies of all project files across two media types, with one copy off-site or in the cloud. Verify that backups are current at least once per week during active data collection and analysis.
Review your data management documentation against the submission requirements of your target journal. Students submitting to PJPCR can review the submission guidelines to confirm that their methods section and supplementary materials meet the documentation standards expected by reviewers.
PJPCR publishes original research across all academic disciplines. If your data is organized, your methods are documented, and your findings are ready for peer review, review the submission guidelines at princeton-jpcr.org/submit.
Frequently asked questions about data management basics for student researchers
What is a codebook and why do student researchers need one?
A codebook is a document that defines every variable in a dataset: its name, what it measures, its units, and the permissible values or response options. Student researchers need one because peer reviewers cannot assess the validity of an analysis conducted on undocumented variables. Without a codebook, a dataset is interpretable only by the person who created it, which fails the reproducibility standard expected by academic journals.
How long does it take to properly organize a research dataset?
For a typical student research project involving survey data or a structured experiment, thorough data organization including folder setup, codebook creation, raw data locking, and change log initialization takes between two and five hours. This investment occurs once and prevents the far larger time cost of reconstructing an undocumented analysis during peer review. Students who use the free tools listed in the best free tools for high school researchers guide can automate portions of this process. The standard peer review timeline at journals such as PJPCR is 2 to 3 months, and a fast-track option is available for students who need a quicker turnaround.
Do student researchers need specialized software to manage their data?
No specialized software is required. A well-organized folder structure, a spreadsheet application such as Google Sheets or Microsoft Excel, and a plain text file for the change log are sufficient for most student research projects. Free statistical tools such as R and JASP include built-in documentation features. The most important data management practices are procedural, not technical, and can be implemented with tools most students already have.
What makes a student research paper's data section publishable rather than just adequate?
A publishable data section allows an independent researcher to replicate the analysis from the raw data to the reported results without contacting the authors. This requires a complete codebook, a documented cleaning process, clearly stated exclusion criteria, and a methods section that describes the data collection procedure in enough detail to be repeated. Papers that meet this standard are substantially more likely to pass peer review than those that report results without explaining how the data was prepared. Reviewing examples of published student work in the published research archive illustrates how methods sections handle data documentation in practice.
What kinds of research does PJPCR accept, and how should data be submitted?
The Princeton Journal of Pre-Collegiate Research accepts original, peer-reviewed research from high school students across all academic disciplines, including the natural sciences, social sciences, humanities, and interdisciplinary fields. Data documentation requirements vary by discipline and are detailed in the submission guidelines. Submission and peer review are free. A publication fee applies for accepted papers. Students uncertain whether their data management meets submission standards are encouraged to review the guidelines before submitting.
Conclusion
Data management basics for student researchers reduce to four non-negotiable practices: preserve raw data without modification, document every variable in a codebook, record every cleaning decision in a change log, and maintain redundant backups throughout the project. These practices are not bureaucratic requirements imposed by journals. They are the conditions under which any empirical finding can be trusted, replicated, or built upon. Reviewers assess data management not as a formality but as evidence of whether the reported results are credible. Students who treat data organization as a core part of the research process, rather than an administrative task to be completed at the end, produce papers that are substantially more likely to survive peer review intact.
If your research is complete, your data is documented, and your findings are ready for independent evaluation, submit your work to PJPCR at princeton-jpcr.org/submit.
Read More

Version control for research documents
By
Princeton Journal of Pre-Collegiate Research
Read more

Digital vs paper lab notebooks for students
By
Princeton Journal of Pre-Collegiate Research
Read more
Data management basics for student researchers
By
Princeton Journal of Pre-Collegiate Research
Read more
How to keep a lab notebook that reviewers trust
By
Princeton Journal of Pre-Collegiate Research
Read more

How to organize research files across a year-long project
By
Princeton Journal of Pre-Collegiate Research
Read more

How to document your data so you can defend it
By
Princeton Journal of Pre-Collegiate Research
Read more
How to write a grant proposal as a student
By
Princeton Journal of Pre-Collegiate Research
Read more
Free resources that replace research funding
By
Princeton Journal of Pre-Collegiate Research
Read more
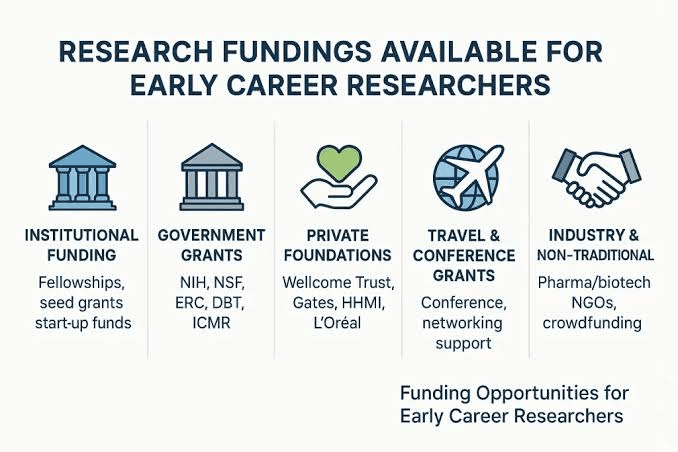
Corporate and nonprofit programs that fund student research
By
Princeton Journal of Pre-Collegiate Research
Read more

Science fair grants and material stipends explained
By
Princeton Journal of Pre-Collegiate Research
Read more

Crowdfunding a student research project: does it work
By
Princeton Journal of Pre-Collegiate Research
Read more

How much does a research project actually cost
By
Princeton Journal of Pre-Collegiate Research
Read more
How to ask your school to fund your project
By
Princeton Journal of Pre-Collegiate Research
Read more

Grants for high school research projects: what exists
By
Princeton Journal of Pre-Collegiate Research
Read more
How to start a research club at your school
By
Princeton Journal of Pre-Collegiate Research
Read more

How to organize a school research symposium
By
Princeton Journal of Pre-Collegiate Research
Read more

Turning a school club into a research pipeline
By
Princeton Journal of Pre-Collegiate Research
Read more

How to start a student research journal at your school
By
Princeton Journal of Pre-Collegiate Research
Read more
How to find a faculty sponsor for a research club
By
Princeton Journal of Pre-Collegiate Research
Read more

How to propose an independent study for research credit
By
Princeton Journal of Pre-Collegiate Research
Read more

Running a peer-review workshop at your school
By
Princeton Journal of Pre-Collegiate Research
Read more